Lesson 1 of 9 · FoundationsRead
Program, Algorithm, Model Compared
How do program, algorithm and model differ? Classic software follows rules a person writes down. An AI model consists of a fixed calculation and numbers set during training.
Your mailbox has a folder you rarely open: spam. It holds emails that promise you a lottery win or announce a parcel you never ordered. Most of the time, the filter puts them there correctly, even though you never explained what junk mail is. How does it know?
An obvious answer is that someone wrote rules for it. Many people picture AI as a giant rulebook filled by experts, one line at a time. That picture fits classic software. It only partly fits most of what people now call AI, because models trained on examples store their behavior in numbers. The difference becomes clearer when you separate three often-confused terms: program, algorithm and model.
Who actually writes the rules?
Suppose you had to build a spam filter yourself. The most obvious approach would be to write down some rules. A made-up but typical filter might apply these three rules, in order:
- If the sender is in your address book, the email goes straight to the inbox.
- If the subject contains the word “prize”, the email goes to spam.
- If it has more than three exclamation marks, it goes to spam too.
Everything else lands in the inbox. This is how a classic program works: a sequence of instructions, laid down by a person, that a computer carries out step by step.
The computer understands none of these rules. It checks whether a condition holds and carries out whatever comes after it. Everything the filter can do is in these lines. To see why an email ended up in spam, look up the rule that fired.
The procedure behind these lines could fit on a slip of paper. A precisely defined procedure of this kind is called an algorithm. Like a recipe, it is a sequence of steps that leads to a result, no matter who follows it. A program is the computer-executable version of that recipe. The comparison only goes so far, however: a recipe may say “a pinch of salt” and leave the exact amount to you, while an algorithm must define every step unambiguously.
Rule filters have a weakness spammers find quickly. If the subject says “PR1ZE” instead of “prize”, the prize rule no longer fires. So a rule for the spelling with the 1 gets added, then one for “p-r-i-z-e”, then one for the next loophole. As the rules get stricter, they also catch genuine emails, such as the message from your sports club about the cup prize.
The programmer Paul Graham described this experience in 2002. By his own account, he had spent about half a year on software that looked for individual spam features. The stricter he made the filters, the more genuine emails they sorted out. Then he tried another route: a filter that derives a value for each word from counted examples. It counts how often each word appears in spam and in normal mail; the value shows how strongly the word points to spam. He set the calculation himself.
A mixing desk instead of a list of rules
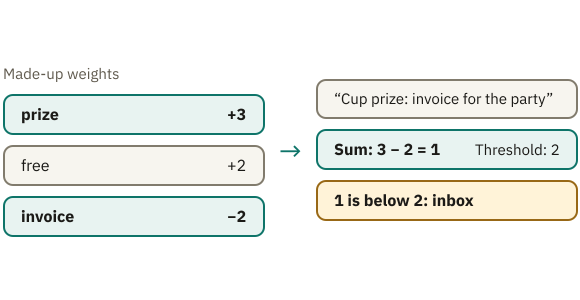
A filter can also decide without a rule such as “If prize, then spam”. Instead, it can work with numbers. Each word receives a weight. The made-up values here are only meant to illustrate the principle: “prize” has a weight of +3, “free” +2 and “invoice” −2. All other words count as 0.
For every email, the filter adds up the weights of the words it contains. It compares this sum with a threshold, here 2: if the sum is above 2, the email counts as spam.
Two emails show how this works. “Free: your prize is waiting” gets +2 for “free” and +3 for “prize”, together 5. That lies far above the threshold of 2: spam.
In the sports club’s email, “Prize at the cup: invoice for the party”, “prize” +3 and “invoice” −2 together make 1, below the threshold: inbox. The figure works through this second email. The sum of all weights decides. Only the final comparison with the threshold is an if-then check. A person made up both the weights and the threshold in this example.
A filter like this is a small model: a fixed calculation whose result depends on stored numbers.
These numbers are the weights. The calculation itself is simple: add up the weights and compare the total with the threshold. A person wrote that calculation, but it says nothing about which words suggest spam. That information lies in the numbers alone. These numbers therefore determine how the filter behaves. Change one of them, and the filter may reach a different verdict without any change to the program code.
Picture a mixing desk in a recording studio, with many sliders set to different positions. Each fader stands for a stored number; its position is that number’s value. For the spam filter, that means adding up the weights and comparing the sum with the threshold. In the example filter, every fader is labelled with a word; in large models, individual numbers usually have no such names. The desk itself provides the fixed calculation. Just as the same desk can make a song sound muffled or clear depending on its settings, the same calculation can recognize spam or do nothing useful, depending on its numbers.
Live demo · try it yourself
The spam filter’s mixing desk
Every fader is a weight. Move the weights and the threshold: the filter re-scores every subject line at once, without a single rule changing.
Weights
If the sum is above the threshold, the email counts as spam.
Subject lines
Try it: which single fader sends the club email to spam? And how do you get it back without letting the advert through?
The weights and the threshold are invented. A real model often has millions to billions of stored numbers, and in large ones usually no single number is named after a word. For real models, training usually sets the numbers, not a person number by number; how they find their positions is what the next section explains.
How the faders find their positions
Training sets the faders: the numbers get adjusted again and again on many examples. Usually a training algorithm sets the numbers, not a person by hand. It needs examples whose correct verdict is already known: thousands of emails that people have marked beforehand as spam or normal mail. The fixed calculation is the one from the mixing desk: it adds up the weights and compares the sum with the threshold, but it does not change any numbers. That calculation, together with the numbers that have been set, forms the model.
At the start, all weights are zero, so the filter considers no word suspicious and lets every email through. Then the same loop runs over and over:
- The filter gets an email and gives its verdict: spam or inbox.
- The training algorithm compares this verdict with the marking a person set for this email.
- If the verdict is wrong, the weights of the words in this email are shifted a small step, so that the email’s sum moves closer to the correct side of the threshold.
- Then the next email comes.
The first training email reads “Free: your prize is waiting” and is marked as spam. The sum is 0. It lies below the threshold of 2, so the filter lets the email through. Wrong. The weights of “free” and “prize” therefore move up a little. After thousands of such rounds, typical advertising words have high numbers, while words from normal mail have low or negative ones.
Think briefly before you read on: during training, a genuine email from your bank turns up, “Your prize: interest on your account”, marked as normal mail. The filter takes it for spam, because “prize” has a high weight by now. What happens to that weight now?
The weight of “prize” drops a little. The weights of the other words in the email, such as “interest”, also fall because those words contributed to the wrong sum. Over time, words that often appear in harmless mail can acquire weights below zero. Advertising emails containing “prize” continue to push its weight up, while harmless emails containing it push the weight down. Eventually, it settles where the two sides balance: high enough to catch most advertising, but not so high that every bank email lands in spam.
So much for the made-up example. Graham took a different route with real mail.
What the filter actually learns
In 2002, Graham showed that values derived from examples could also work with real mail. His method took a simpler route: counting. For each word, he counted how often it appeared in the spam collection and how often it appeared in normal mail. A word found mostly in spam received a high number, much like the weights above but calculated differently. The examples supplied the numbers; Graham chose how to combine them and which limits to apply. In Graham’s own test, this filter missed fewer than 5 in 1,000 spam emails and sorted out no genuine email. That was a measurement on his own mail, not a general study.
One level deeper: what Graham still set by hand
Graham’s filter did not adjust weights step by step, unlike the loop. Instead, it divided each word count by the number of emails in that collection. The result answers how likely an email with that word is to be spam. An invented example, not Graham’s data: a word appears in 100 of 1,000 spam emails and in 5 of 1,000 normal ones. Graham doubled the 5 to 10. That gives 100 of 1,000, or 0.1, for spam and 10 of 1,000, or 0.01, for normal mail. The spam share is 0.1 divided by (0.1 + 0.01), about 0.9. Words that almost only appear in spam land near 1, words from normal mail near 0.
These word values came from the data. Graham himself decided how to calculate with them, by his own account largely through trial and error:
- He doubled every count from the normal mail. This pushes the values of words that occasionally appear in genuine mail a little lower, and protects against false positives: genuine emails in spam.
- He only considered words that appeared more than five times in total.
- No value went below 0.01 or above 0.99. No single word was ever completely certain.
- A word the filter had never seen got 0.4, a value Graham found, by his own account, through trial and error. Below 0.5, it leans towards harmless.
When a new email arrived, the filter used only its 15 most striking words, those furthest from 0.5. It combined these 15 values with Bayes’ rule, a formula from probability theory, into one value. The formula amplifies agreement: if most of the 15 words sit near 1, so does the overall value, and vice versa. If the overall value was above 0.9, the email counted as spam. According to Graham, the exact threshold hardly mattered, because few emails ended up in the middle.
Only the basic idea carries over to the example: Graham’s word values also came from examples. His calculation was different. He used Bayes’ rule to combine them into a probability and compared it with 0.9, so the threshold of 2 from the example does not apply. Graham chose the details of this calculation himself: the doubling, the minimum count, the limits 0.01 and 0.99, the value 0.4, the 15 words and the threshold.
People often say that a filter like this has learned what spam is; the overall approach is called machine learning. But “learned” needs a qualification: the filter has not understood what advertising is. In both versions, only the numbers change. The example filter adjusts them until the errors are small, while Graham’s filter obtains them by counting. Most of today’s training algorithms follow this pattern: measure the error, adjust the numbers a little, repeat. The big difference is quantity: large models involve billions of numbers, the example only three weights.
Where the mixing desk reaches its limit
The mixing-desk comparison has its limits. On a real desk, the faders have names such as bass, treble or volume. A large model’s parameters, that is, its stored numbers, do not come with such labels, and there are an enormous number of them. GPT-3, a language model from 2020 that writes text, has around 175 billion parameters. It is hard to say what any one of those numbers does, because the model’s behavior mostly emerges from many of them working together. By contrast, the example filter has only three words, so you can still inspect every weight. That is what makes it useful for explaining the principle.
Why the rulebook idea is so persistent
Much of what you use on a computer every day follows fixed, written instructions, from spreadsheets and bank software to the systems that control traffic lights at junctions. For a long time, AI worked this way too. Expert systems emerged in the 1960s and 1970s, became widespread by the 1980s and were among the first truly successful forms of AI software. Designed to reproduce the decisions of human experts in a particular field, they were essentially large collections of if-then rules.
So if you picture AI as a rulebook, the image in your head is one that really existed. It does not describe the trained models that are usually meant today.
The difference matters when something goes wrong. In a rule-based filter, you can find and change the instruction that produced the verdict. A purely trained model has no equivalent line. It consists of a fixed calculation and a set of numbers; if a spam filter learned only from examples and has no built-in rules, those numbers determine its behavior. In the small example, the weight of “prize” still shows that the filter treats the word as suspicious. In a model with billions of unnamed parameters, no single number will usually carry that meaning.
The examples can also cause errors in a trained model. Suppose the markers had marked every email with the word “invoice” as spam, even though those emails were harmless. Then the training algorithm would have pushed the weight of “invoice” up, and the filter would have picked up exactly that. The error can be corrected through the numbers: by training again with corrected examples.
Back to the question from the start: how does your spam filter know what advertising is? Its knowledge comes from numbers that a training algorithm set using many marked examples. If the filter also has fixed rules, some of that knowledge is written in program instructions and the rest is stored in numbers. Nobody wrote down a list of suspicious words. People chose the calculation, the training algorithm, the threshold and the marked examples. Once training ends, the faders stay put. From then on, the filter uses the same fixed numbers for every email: an email goes in, a verdict comes out. The same email always gets the same verdict; this filter rolls no dice. If someone changes the faders, by retraining or by hand, the same email can get a different verdict than it got before.
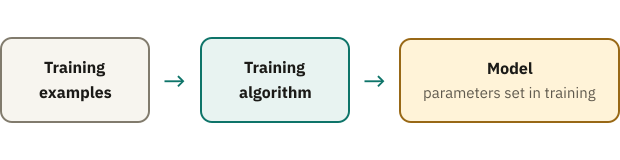
A model that writes text also has fixed numbers: billions of them. The next lesson, Input and Output, explains why you can still get different answers to the same question and where chance comes into play.
Explain it more simply
- Explain more simplyCore idea and an everyday comparison
- With an exampleOne concrete example, step by step
- In more detailEvery step on its own, in plain words
Recall moment
What stayed with you?
Answer without scrolling back. This is not a grade; the point is to retrieve what you learned from memory once. As soon as you pick an answer, you see whether it is right.
Preparing questions …
Questions from the community
Something still unclear? Ask your question about this lesson on the community board. Other learners and the project answer there, and you can see what others have already asked.