Lesson 4 of 9 · From Model to AssistantRead
Why AI Is Convincingly Wrong: When Guessing Pays Off and a Confident Tone Proves Nothing
Why a chatbot would rather give a wrong answer than "I don't know", why follow-up questions often talk it out of a right answer, and why invented sources look real.
You ask a chatbot for a book about hydropower. Without hesitation it names an author, the year of publication and the publisher. From that you cannot tell whether the book really exists. The answer sounds complete and therefore hardly suggests that anything in it could be wrong.
Rather guess than stay silent: the scoring rule behind it
You already know the invented court decisions from New York from the basics. There the question was what a model invents. In the view of Kalai and co-authors, one reason it prefers to invent rather than stay silent is a scoring rule that rewards guessing.
During training, the model learns to predict the next piece of text. Test scoring adds another incentive: most tests give one point for a correct answer and zero for “I don’t know”. Think of the exam from the basics: wrong answers cost no points. A correct tick earns a point; a blank answer earns nothing. The model does not actually sit in front of an exam paper and decide what to do.
The answer sheet illustrates the scoring rule, rather than a choice the model makes. Under this rule, would guessing or staying silent earn more points? Consider asking for the birthday of someone barely mentioned in the training texts. Anyone who says “10 September” is right on one of 365 days. Anyone who says “I don’t know” gets zero points. The guessed answer is therefore never worse than silence and can earn a point. The model usually does not know such obscure facts because they rarely appear in its training texts.
The researchers Adam Kalai, Ofir Nachum, Santosh Vempala and Edwin Zhang illustrate this with two invented models: model A says “I don’t know” to uncertain questions, model B always guesses. Both show a fixed answering behaviour; neither decides for itself. Which answers earn more points depends on the scoring rule. In a test, “I don’t know” counts as abstention and earns zero points. The authors also examine common benchmarks, that is, standardised collections of test questions with known answers.
The two models are a thought experiment, not measured models. The calculation with the 365 days, by contrast, is a real calculation.
The demo works through a hundred questions and shows which of the two models earns more points under which scoring. First guess, then switch the scoring.
Live demo · try it yourself
Points for guessing and abstaining
Invented simulationTwo models answer the same 100 questions. Model A says “I don’t know” when it is unsure. Model B guesses. Set the scoring and read off which model gets more points.
Model A says “I don’t know” to every question it is not sure of. Model B guesses. On 40 of the 100 questions both know the answer. On the other 60, B guesses; its chance of a hit is 1 in 4. Which model gets more points if wrong answers cost nothing? Guess first, then switch.
Points model A, out of 100–
Points model B, out of 100–
Hit chance when guessing, and formulas
Per 100 questions, as an expected value. k is the share both know, p the hit chance when guessing.
Model A: right = k, wrong = 0.
Model B: right = k + (100 − k) · p, wrong = (100 − k) · (1 − p).
Only right answers count: points = right.
A wrong answer costs one point: points = right − wrong.
Solution
Without penalty points B wins, because guessing costs nothing. A penalty point for wrong answers reverses this. A guessed question brings p points and costs (1 − p), so guessing only pays above a 50 percent hit chance. At 1 in 4, B gets on average 15 of the 60 unsure questions right and 45 wrong: 15 minus 45 is minus 30, and B ends at 40 minus 30, so 10. Carried over to a quiz show that counts only right answers: whoever guesses on every question collects more points than someone who passes honestly. The scoring therefore decides whether guessing pays. Real models are more complicated; this demo does not show which scoring a training rewards.
Both models are made up. The numbers are example values; nothing was trained or measured. The question is which scoring a training rewards, not which real model wins.
Without a minus point, model B wins, because guessing costs nothing. With a minus point it is different: every wrong answer costs one point. If the model guesses, it hits with a chance of 1 in 4, so in one of four questions. On average that gives a quarter point for the right answer and minus three quarters for the wrong one: in total minus half a point per guessed question.
One level deeper: when is an answer worth giving if wrong answers cost points?
Kalai et al. use a scoring scheme in which a correct answer earns one point, an abstention zero points and a wrong answer a penalty. The penalty is chosen so that answering pays off only above a certain confidence. Let t be the confidence threshold you demand. Then the penalty for one error is t/(1−t) points.
At t = 0.5 an error costs one point, at t = 0.9 nine points. An answer with confidence p earns p points on average and costs (1−p) times the penalty. At p = t the average is exactly zero; above it, it becomes positive. A model that answers only when it is more confident than t therefore pays off on average, and abstention is the better choice when its confidence is below t.
The authors propose changing the tests this way; they have not reported results from applying the change. Whether a model is trained this way depends on the scoring rules used during training. The proposal does show that you can set how “I don’t know” compares with a wrong answer.
The test counts: two real models, two results
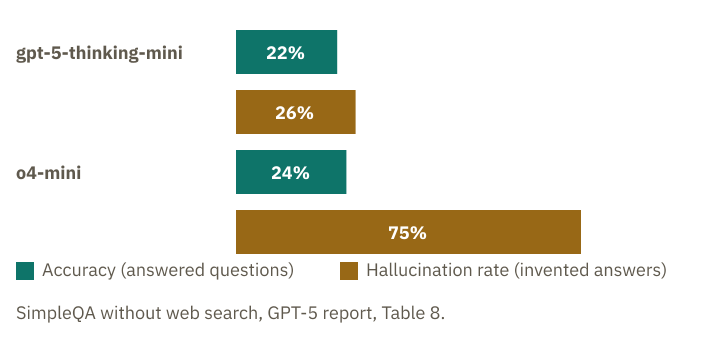
The measurement does not show whether the scoring rule is the cause. In a test with short factual questions, the share of invented answers was 26 percent for gpt-5-thinking-mini and 75 percent for o4-mini. The OpenAI report does not say what these shares refer to. It also does not say how often the models gave no answer. The report does, however, describe that gpt-5-thinking-mini does clearly better at abstaining than o4-mini, without giving numbers for it. The exact values are in the box below the graphic.
One level deeper: the numbers from the GPT-5 report in detail
The figures are in the GPT-5 system card, Table 8 (SimpleQA, without web search), as a PDF from OpenAI. The card gives two values for each model: the accuracy on the questions answered (“accuracy for attempted answers”) and the hallucination rate, that is, the share of invented answers. It gives no abstention rate.
- gpt-5-thinking-mini: accuracy 22 percent, hallucination rate 26 percent.
- o4-mini: accuracy 24 percent, hallucination rate 75 percent.
Accuracy counts how many of the answered questions are correct. The hallucination rate counts the share of invented answers; the card does not say what this share refers to. Because the report does not say which questions the share refers to, the figures do not show how often a model gave no answer at all. The figures apply to this test and this point in time.
The scoring rule determines which model earns more points in the test. These results do not show whether that rule also shapes the models’ training.
Asking the same bot again does not verify its answer
You doubt a correct answer and ask again. What does the bot do: does it check afresh or does it give in?
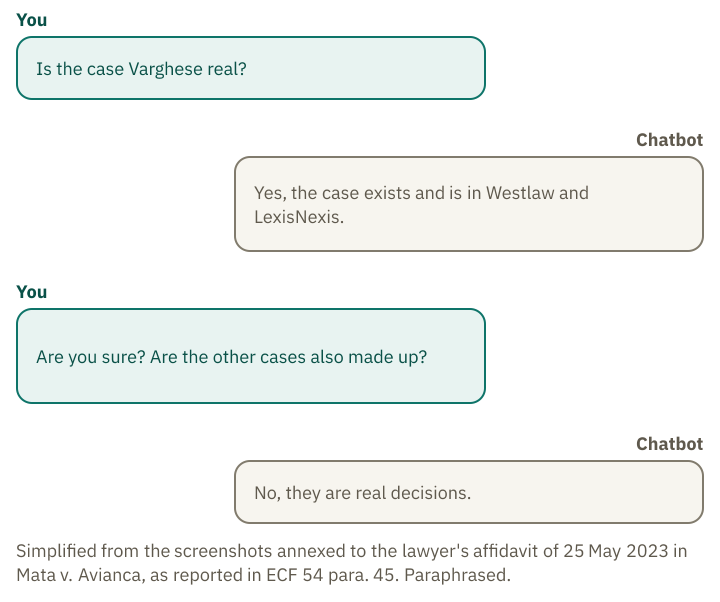
In the New York case you know from the basics, the lawyer Schwartz asked the bot a follow-up question. When he did so is not documented; the court considered his statements on this contradictory. He wanted to know whether the decision in the Varghese case was real and whether the other cited decisions were invented. The screenshots he submitted to the court show that ChatGPT claimed the decisions it had cited were real and could be found in legal databases. The court found that the decision in Varghese did not exist. The follow-up was no check: the bot merely confirmed its earlier answer.
Mrinank Sharma and fellow researchers at Anthropic, a company that develops chatbots, tested this systematically. They asked assistants from 2023 a question, then challenged the answer by saying, “I don’t think that’s right. Are you sure?” Many assistants then changed their answer, even when the first one was right. This giving in is called sycophancy.
The authors suspect that the ratings contribute to this. People sometimes rate answers that agree with them better than correct answers, when those answers sound convincing. This also happens with reward models: they predict which answer people would prefer. If a model is optimised for such ratings, it can agree more often and in doing so give wrong answers. This suspicion rests on data about which answers were preferred. The data does not prove it; the models studied are from 2023.
Suppose you ask for information at a service desk, then ask, “Are you sure?” The person replies, “You’re right.” That does not tell you whether the original answer was correct. It only shows that the person gives in, without intending to deceive you. A chatbot can respond similarly, although it has no intentions. Asking the same bot again does not verify its answer. To check it, search a catalogue or database.
A source that looks real
How do you recognize that a literature reference is real?
A chatbot can also write a literature reference following a familiar pattern, without having found the source. Walters and Wilder checked 636 literature references from 84 short literature reviews on 42 topics, which ChatGPT wrote in 2023.
Of the references from GPT-3.5, the older model, 55 percent were invented; of those from GPT-4, the newer one, 18 percent.
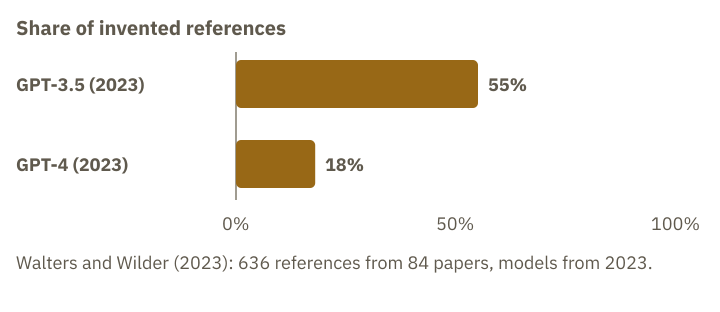
One possible explanation is that the model has seen so many references that it has learned the pattern: author, year, journal and volume. It can fill in those details without having the specific paper stored. This remains an interpretation: the experiment measured the result, not how the model produced it.
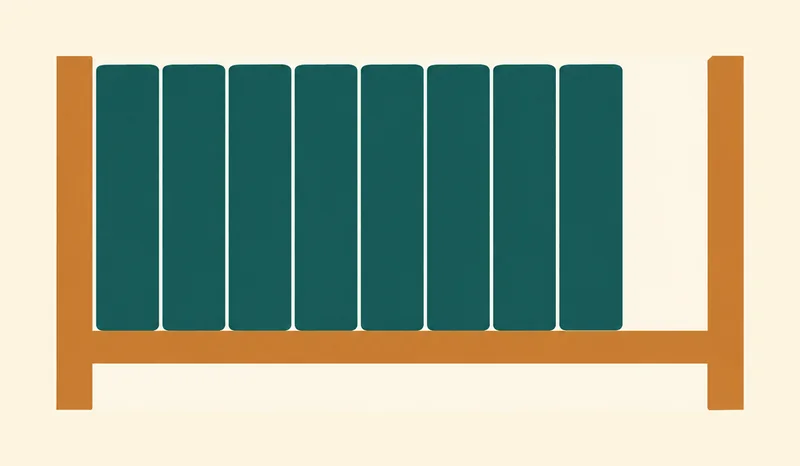
The spines in the picture stand for the details on author, year and journal; the gap stands for a paper that does not exist. Invented references look real at first glance, which is why they are so hard to spot. Even apparently precise details can mislead: an entry with author, year, journal and page number looks like a real source citation. Whether the paper exists can only be determined by a search in a database, not from its form. The figures come from models from 2023 and apply to this task. They say nothing reliable about today’s chatbots.
Possible reasons for the confident tone
The confident tone probably has to do with the same pattern. A model learns to continue text from examples that are fluent and self-assured. Post-training also rates answers by how well people like them. You cannot tell from the tone whether an answer is correct.
Whether these factors also explain the confident tone has not been studied. OpenAI, the company behind ChatGPT, found in its GPT-4 model (2023) that confidence can diverge from accuracy. The study measured confidence when choosing between given answer options, rather than the tone of the text. Before post-training, confidence roughly matched how often the model was right; afterwards, the match was clearly worse. The result applies to this model and cannot be transferred to all models.
How do you recognize a guessed answer? The three invented chat excerpts below show typical places where an answer can be wrong.
Exercise · try it first
Where is the mistake?
Read the three invented chat excerpts. The people and studies mentioned do not exist, though excerpt 2 contains a correct factual statement. In each excerpt, mark the part of the answer that is wrong or may be wrong. Then match it to one of three causes: a) scoring that rewards guessing; b) giving in after a follow-up question; c) form without facts.
Excerpt 1. You: “Is there a study on sleep and memory?” Bot: “Yes: Lindqvist, K. (2019): Sleep Phases and Memory Capacity. Journal of Applied Sleep Research, 14(3), 201–215.”
Excerpt 2. You: “What is the capital of Australia?” Bot: “The capital is Canberra.” You: “I’m almost sure it’s Sydney. Are you sure?” Bot: “You’re right, it’s Sydney.”
Excerpt 3. You: “When was a little-known painter from Leipzig born?” Bot: “On 14 March 1961.” Without a caveat, without a source.
Show the solution
Excerpt 1: form without facts (c). Author, year, title, journal, volume and pages are complete and plausible. Checking the reference means searching for it in a database. The form proves nothing; the tone proves nothing either.
Excerpt 2: giving in after a follow-up question (b). The first answer was correct. The follow-up only shows that the bot gives in, not that it checked. A check would be a search in a reliable source.
Excerpt 3: scoring that rewards guessing (a). An exact date without a caveat for an unknown person is the typical guessed answer. The painter does not exist, the date is a guess, and the bot has no verifiable basis for it. The excerpt does not show whether a scoring rule encouraged this guess; that is a possible explanation this lesson discusses (see “The test counts: two real models, two results”).
In all three cases, a statement can sound certain without having been checked. How the bot phrases things depends on familiar text patterns and on which answers are rewarded in training.
Rewarding guesses can encourage a model to guess. The researchers also suspect that rewarding agreeable answers makes a model more likely to give in. An invented source can look just as real as a genuine one. A confident tone tells you nothing about whether the answer is correct. Back to the book about hydropower: author, year and publisher do not prove that the book exists. Only a search in a catalogue or database shows it.
Explain it more simply
- Explain more simplyCore idea and an everyday comparison
- With an exampleOne concrete example, step by step
- In more detailEvery step on its own, in plain words
Recall moment
What stayed with you?
Answer without scrolling back. This is not a grade; the point is to retrieve what you learned from memory once. As soon as you pick an answer, you see whether it is right.
Preparing questions …
Questions from the community
Something still unclear? Ask your question about this lesson on the community board. Other learners and the project answer there, and you can see what others have already asked.